Built From Scratch in Guwahati: The Bootstrapped Lab Putting Northeast India on the AI Foundation-Model Map
GUWAHATI — In a corner of India’s AI landscape that rarely makes it into national headlines, a small, self-funded lab has just pulled off something that puts it in a very short list of Indian...

GUWAHATI — In a corner of India’s AI landscape that rarely makes it into national headlines, a small, self-funded lab has just pulled off something that puts it in a very short list of Indian companies: it built a generative language model completely from scratch — no borrowed weights, no fine-tuned shortcuts — and gave it away for free.
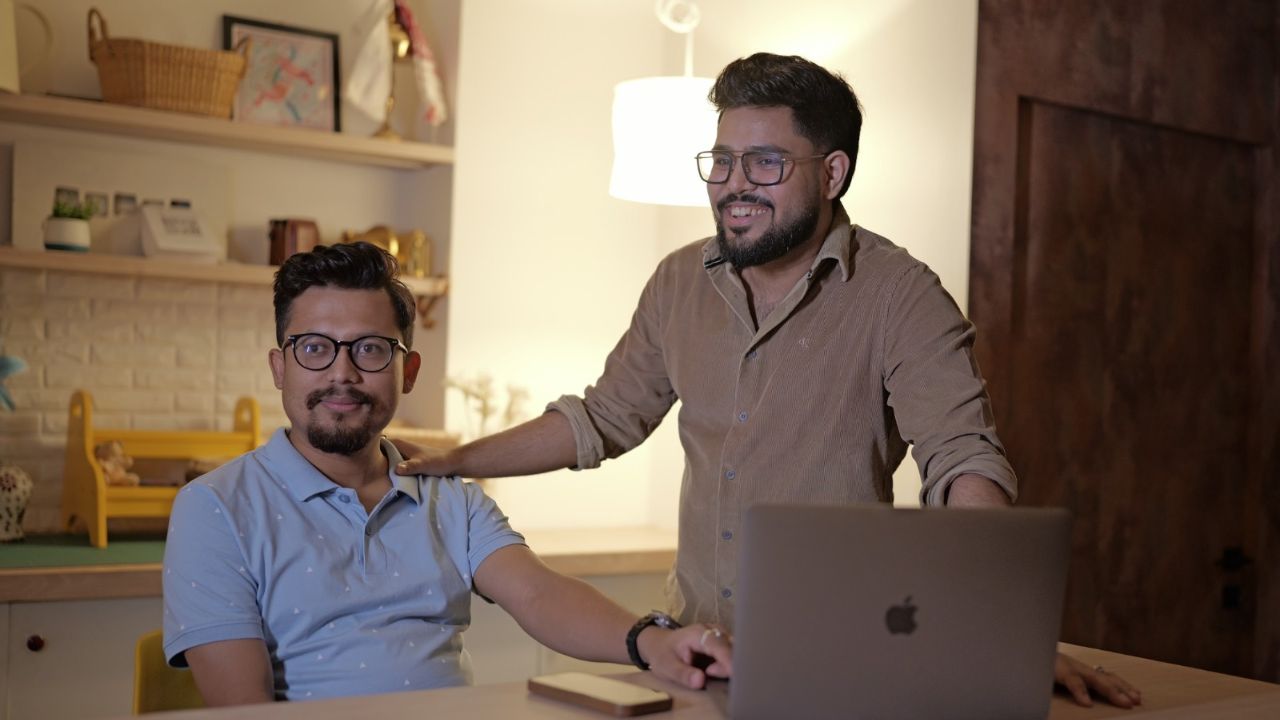
Navdyut AI Labs, based here in Assam and co-founded by Dicom Pathak and Lakshya J Bora, has open-sourced a 240-million-parameter foundational model, the newest in a family that started at just 15 million parameters and has been scaling up ever since. The release marks the first time an AI lab in Northeast India has trained and open-sourced a generative foundational model built entirely from the ground up — not adapted from an existing one, but engineered from first principles.
That distinction matters more than it might sound. Most AI startups, in India and globally, build on top of open-weight models released by giants like Meta or Google — fine-tuning what already exists rather than training anything new. Doing it from scratch means building your own tokenizer, designing your own training pipeline, and getting the underlying math right without a safety net. Navdyut’s team had to master Maximal Update Parameterization (muP) and gradient control, and hew closely to Chinchilla-optimal scaling laws — the compute-efficiency playbook that governs how much data a model of a given size should actually be trained on to perform well.
“While many labs focus on bigger models, we focus on relevant models. The biggest challenge in the industry right now boils down to control, inference cost, and the global chip shortage. By training from scratch, we dictate exactly what goes into the AI’s diet.” — Dicom Pathak, Co-founder, Navdyut AI Labs
Betting Against the Chip Shortage
That last point is where Navdyut’s strategy gets genuinely interesting — and where it diverges from almost everyone else in the room.
The overwhelming majority of AI infrastructure today runs on Nvidia’s CUDA ecosystem, a dependency that has become both a technical convenience and, increasingly, a strategic liability as global chip supply tightens. Navdyut is deliberately engineering its models for AMD inference instead — a bet that the industry’s CUDA lock-in is a bottleneck worth escaping now, rather than later.
“We are engineering these models specifically for AMD inference to escape the CUDA bottleneck, enabling seamless transitions and significantly cheaper real-world deployment.” — Dicom Pathak
It’s a quietly ambitious thesis: that the next wave of useful AI won’t come from whoever has the most GPUs, but from whoever can make the fewest parameters do the most work — and run them on hardware that isn’t rationed by a global shortage.
The Roadmap: From Research Engine to “Lego Piece” AI
The 240M model that’s now live on Hugging Face isn’t the destination — it’s proof that the underlying infrastructure works. Navdyut’s roadmap pushes toward 480M and then 960M parameter models, with the 960M scale seen internally as the point where the models cross into genuine production utility: agentic tool-calling, and what’s known as Domain Adaptive Pre-Training, where a model is deeply specialized for a particular field rather than trying to know a little about everything.
The long-term vision is what the lab calls “Modular Agentic Foundational Models” — small, task-specific models designed to snap together like building blocks rather than one enormous general-purpose system trying to do everything at once. The goal, according to the lab, is for a specialized 960M-parameter model to match the performance of a much larger 1.5B general-purpose model, while cutting inference compute by as much as half and making edge-device deployment realistic.
After the 960M milestone, the roadmap extends into the 1.5B–8B parameter range — the zone the lab describes as the sweet spot between low compute cost and enterprise-grade capability.
Why This Matters Beyond One Lab
There’s a broader story here about where India’s AI ambitions actually take root. Much of the conversation around Indian AI has centered on Bengaluru, Hyderabad, and the metros with venture capital density and marquee research partnerships. Navdyut AI Labs is neither venture-funded nor metro-based — it’s bootstrapped, and it’s in Guwahati.
That a two-person, regional, self-funded founding team has managed to join what Navdyut describes as a “single-digit tier” of Indian organizations training genuine from-scratch foundational models is itself worth attention, independent of where the technology roadmap ultimately lands. It suggests the resources needed to do frontier-adjacent AI research — while still substantial — are no longer exclusively gated behind large funding rounds and metro-city ecosystems.
Whether Navdyut’s AMD-first, modular-agentic bet pays off at scale remains to be tested — the 960M and larger models are still ahead, not behind. But the 240M release is a real, verifiable artifact: it’s public, it’s downloadable, and it’s the first of its kind to come out of the region.
The 240M model and the rest of Navdyut AI Labs’ model family are available on Hugging Face at huggingface.co/dicompathak. More on the lab is at navdyut.com.